Headline numbers
Percentages are of the 7,920 domains whose robots.txt request got a usable answer (a file, a 4xx status, or an HTML page instead of a file). The other 2,079 domains in the list did not answer, answered with a server error or do not run a website at all (many top domains are CDNs, ad or API hosts).
What the data says
- The most blocked crawler is CCBot (13.8% of sites); the least blocked is Googlebot (2.1%).
- Training and search are treated differently: GPTBot is fully blocked by 12.9% of sites but OpenAI's search crawler OAI-SearchBot by 5.4%; ClaudeBot by 12.3% versus 5.4% for Claude-SearchBot.
- 5.9% of sites block both GPTBot and ClaudeBot while leaving OAI-SearchBot and Claude-SearchBot allowed: the “no training, but stay citable” setup.
- Google-Extended, the token that controls Gemini training without affecting Google Search, is blocked by 11.2% of sites.
- 14.2% of sites block at least one AI crawler by name, and 2.0% block every crawler we track, usually with a blanket
User-agent: */Disallow: /. - 12.5% of sites refuse the robots.txt request itself (HTTP 401 or 403), often a bot-protection layer: under RFC 9309 that formally means “no restriction”, but such sites usually filter crawlers at the network level instead.
Block rate of each AI crawler
Share of sites whose robots.txt disallows both the home page and an arbitrary page for the crawler, either in a group that names it or through the generic User-agent: * group.
User-agent: *Embed this chart
PNG version refreshed after every run, free to reuse under CC BY 4.0 with the credit link:
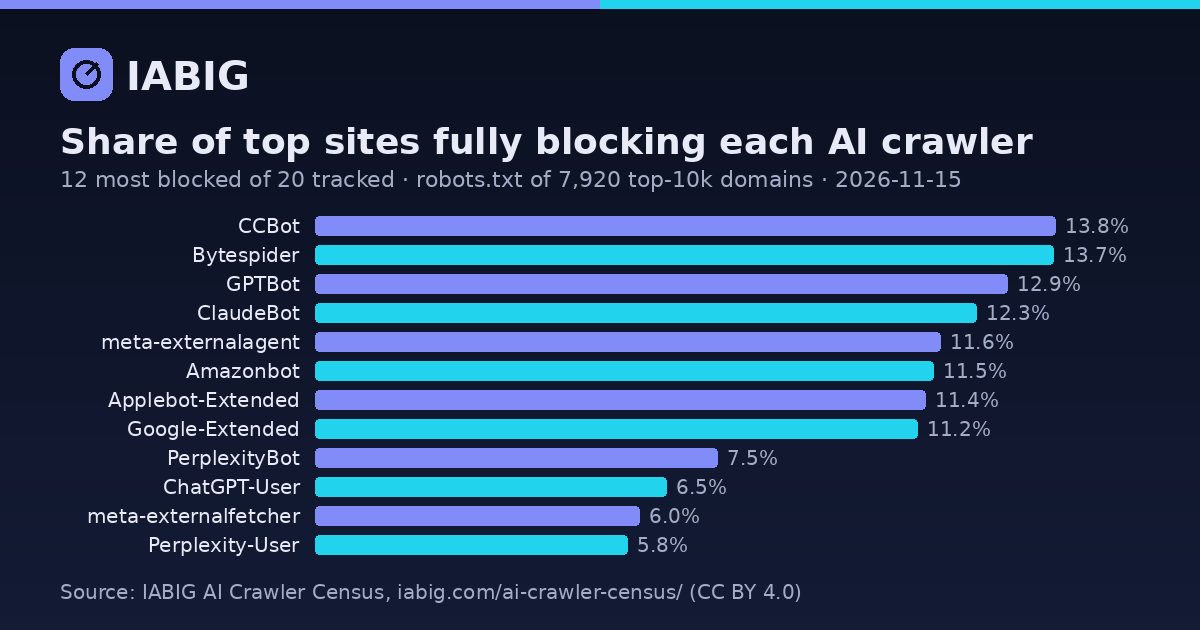
| Crawler | Fully blocked | …by name | Partially restricted | Named in robots.txt |
|---|---|---|---|---|
| CCBot Common Crawl · Training | 13.8% | 10.8% | 1.6% | 13.1% |
| Bytespider ByteDance · Training | 13.7% | 10.7% | 1.2% | 12.1% |
| GPTBot OpenAI · Training | 12.9% | 10.2% | 3.0% | 15.0% |
| ClaudeBot Anthropic · Training | 12.3% | 9.4% | 2.4% | 13.2% |
| meta-externalagent Meta · Training | 11.6% | 8.6% | 1.3% | 10.5% |
| Amazonbot Amazon · Training | 11.5% | 8.5% | 1.5% | 10.5% |
| Applebot-Extended Apple · Training | 11.4% | 8.4% | 1.4% | 10.4% |
| Google-Extended Google · Training | 11.2% | 8.4% | 2.3% | 12.5% |
| PerplexityBot Perplexity · Search | 7.5% | 4.7% | 2.6% | 9.2% |
| ChatGPT-User OpenAI · Browsing | 6.5% | 3.8% | 2.8% | 8.4% |
| meta-externalfetcher Meta · Browsing | 6.0% | 2.9% | 0.8% | 3.9% |
| Perplexity-User Perplexity · Browsing | 5.8% | 2.8% | 1.5% | 5.0% |
| DuckAssistBot DuckDuckGo · Search | 5.8% | 2.7% | 1.2% | 4.1% |
| Claude-User Anthropic · Browsing | 5.7% | 2.8% | 1.6% | 5.1% |
| MistralAI-User Mistral AI · Browsing | 5.4% | 2.3% | 0.8% | 3.3% |
| Claude-SearchBot Anthropic · Search | 5.4% | 2.4% | 1.8% | 4.8% |
| OAI-SearchBot OpenAI · Search | 5.4% | 2.6% | 2.8% | 7.3% |
| Applebot Apple · Search | 3.8% | 1.2% | 1.8% | 3.8% |
| Bingbot Microsoft · Search | 2.7% | 0.5% | 3.6% | 5.7% |
| Googlebot Google · Search | 2.1% | 0.1% | 4.8% | 6.9% |
By popularity rank
Cumulative tranches of the Tranco ranking: the top 100 are also part of the top 1,000, and so on.
| Top 100 | Top 1,000 | Top 10,000 | |
|---|---|---|---|
| Domains with a readable answer | 71 | 727 | 7,920 |
| Serve a robots.txt file | 67.6% | 65.5% | 69.5% |
| Name at least one AI crawler | 26.8% | 21.9% | 19.3% |
| Block all training crawlers | 15.5% | 8.1% | 7.9% |
| Publish an llms.txt | 12.7% | 17.1% | 12.6% |
| Fully block GPTBot | 19.7% | 13.6% | 12.9% |
| Fully block ClaudeBot | 19.7% | 13.6% | 12.3% |
| Fully block CCBot | 19.7% | 15.1% | 13.8% |
| Fully block Google-Extended | 19.7% | 11.8% | 11.2% |
| Fully block PerplexityBot | 21.1% | 11.0% | 7.5% |
| Fully block OAI-SearchBot | 15.5% | 7.8% | 5.4% |
By top-level domain
Top-level domains with at least 30 domains giving a readable answer.
| TLD | Domains | robots.txt | Block GPTBot | Block all training | llms.txt |
|---|---|---|---|---|---|
| .com | 4,054 | 70.3% | 12.8% | 7.5% | 16.3% |
| .net | 412 | 62.9% | 15.5% | 11.9% | 9.2% |
| .org | 407 | 76.4% | 14.0% | 8.8% | 8.4% |
| .ru | 216 | 64.8% | 7.9% | 3.7% | 6.9% |
| .jp | 173 | 57.2% | 9.8% | 5.8% | 3.5% |
| .de | 161 | 75.2% | 21.1% | 8.7% | 9.9% |
| .io | 151 | 66.2% | 9.3% | 7.9% | 31.8% |
| .edu | 114 | 81.6% | 5.3% | 3.5% | 3.5% |
| .gov | 109 | 65.1% | 2.8% | 1.8% | 0.9% |
| .br | 92 | 64.1% | 6.5% | 3.3% | 13.0% |
| .fr | 91 | 75.8% | 26.4% | 14.3% | 2.2% |
| .uk | 82 | 67.1% | 17.1% | 7.3% | 4.9% |
| .it | 77 | 70.1% | 20.8% | 5.2% | 9.1% |
| .in | 75 | 46.7% | 5.3% | 5.3% | 9.3% |
| .cn | 71 | 43.7% | 2.8% | 2.8% | 2.8% |
Change since the previous run
Compared on the 7,666 domains present, and readable, in both this run and the run of November 8, 2026, so that changes in the composition of the Tranco list do not distort the trend. llms.txt: 953 → 968 sites.
| Crawler | Before | Now | Change (points) | Newly blocked | Unblocked |
|---|---|---|---|---|---|
| Google-Extended | 11.3% | 11.1% | -0.2% | 5 | 18 |
| GPTBot | 12.9% | 12.8% | -0.1% | 6 | 15 |
| PerplexityBot | 7.7% | 7.6% | -0.1% | 2 | 9 |
| ChatGPT-User | 6.6% | 6.6% | -0.1% | 4 | 9 |
| ClaudeBot | 12.3% | 12.3% | -0.1% | 7 | 11 |
| Amazonbot | 11.4% | 11.5% | +0.0% | 10 | 6 |
| CCBot | 13.8% | 13.7% | -0.0% | 8 | 12 |
| Claude-User | 5.7% | 5.7% | +0.0% | 4 | 1 |
| meta-externalagent | 11.6% | 11.6% | +0.0% | 10 | 7 |
| DuckAssistBot | 5.8% | 5.8% | +0.0% | 4 | 1 |
| OAI-SearchBot | 5.4% | 5.4% | -0.0% | 3 | 5 |
| Claude-SearchBot | 5.4% | 5.4% | +0.0% | 4 | 2 |
| MistralAI-User | 5.4% | 5.5% | +0.0% | 3 | 1 |
| Perplexity-User | 5.9% | 5.9% | +0.0% | 4 | 3 |
| Googlebot | 2.1% | 2.1% | -0.0% | 0 | 1 |
| Bingbot | 2.7% | 2.7% | -0.0% | 0 | 1 |
| Applebot | 3.8% | 3.8% | -0.0% | 0 | 1 |
| Bytespider | 13.7% | 13.7% | -0.0% | 10 | 11 |
| Applebot-Extended | 11.3% | 11.3% | +0.0% | 7 | 7 |
| meta-externalfetcher | 6.1% | 6.1% | +0.0% | 4 | 4 |
History
| Run | Domains | GPTBot | ClaudeBot | All training | llms.txt |
|---|---|---|---|---|---|
| November 15, 2026 | 7,920 | 12.9% | 12.3% | 7.9% | 12.6% |
| November 8, 2026 | 7,924 | 12.8% | 12.2% | 7.7% | 12.3% |
| November 6, 2026 | 7,920 | 12.8% | 12.3% | 7.7% | 12.3% |
Between two censuses
The AI policy change tracker re-reads the robots.txt and llms.txt of the top 2,000 domains twice a day: 19 AI-relevant change(s) in the last 7 days.
- cnbc.com (#486) blocked GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, Claude-SearchBot, Claude-User, PerplexityBot, Perplexity-User, Google-Extended, Applebot-Extended, meta-externalagent, Amazonbot, CCBot, Bytespider; partially restricted Googlebot (November 10, 2026)
- unesco.org (#614) removed its llms.txt (November 15, 2026)
- techcrunch.com (#633) unblocked ChatGPT-User, Google-Extended (November 13, 2026)
- fiverr.com (#828) partially restricted OAI-SearchBot, ChatGPT-User, Claude-SearchBot, Claude-User, PerplexityBot, Perplexity-User, Google-Extended, Applebot-Extended, MistralAI-User, DuckAssistBot (November 11, 2026)
- hbr.org (#912) blocked ClaudeBot, Applebot-Extended, meta-externalagent, meta-externalfetcher, Bytespider (November 13, 2026)
Beyond robots.txt, the AI-Readiness Index audits the home pages of the same 10,000 domains: server-rendered text, structured data, Open Graph, headings, sitemap and llms.txt.
Check one domain from the census
Look up how a domain of the list was classified in the latest run, crawler by crawler. To analyse any other site, use the AI visibility checker.
Download the data
Aggregates only (no per-domain rows), under the CC BY 4.0 licence: credit “IABIG AI Crawler Census, iabig.com” with a link to this page.
- census.json — latest run (all counts, rank tranches, TLDs, change) and the history of every run
- census.csv — block counts and rates per crawler and rank tranche, latest run
Methodology
Domain list. Each run downloads the latest daily Tranco list (registrable domains, combined from Chrome UX Report, Cloudflare Radar, Cisco Umbrella, Majestic and Farsight over 30 days) and keeps the top 10,000. Tranco ranks domains, not websites: a domain such as a CDN or an API endpoint can be very popular without serving pages.
Requests. For each domain we request https://domain/robots.txt, then https://www.domain/robots.txt, then http://domain/robots.txt until one answers, following up to 5 redirects, reading at most 512 KiB, with a 6-second connection timeout. We then request /llms.txt on the host that answered. Requests come from one server in Europe, 12 at a time, with the User-Agent iabig-census/1.0 (+https://iabig.com/ai-crawler-census/). Sites that answer differently by country, block our IP or serve other content to known AI crawlers are measured as they answered us.
Interpretation. robots.txt files are parsed with the same RFC 9309 parser as our robots.txt tester (most specific group, longest match, Allow wins ties, * and $ wildcards). For each of the 20 crawlers we track:
- Fully blocked
- The home page
/and an arbitrary page are both disallowed, either by a group naming the crawler (“by name”) or by theUser-agent: *group. - Partially restricted
- Not fully blocked, but a group naming the crawler disallows something, or arbitrary pages are disallowed while the home page is allowed.
- Named
- The crawler's token appears in a
User-agentline, whatever the rules.
A 4xx answer means “no robots.txt” and an HTML page served instead of a file has no usable rules: both count as allowing everything, as RFC 9309 specifies. Server errors (5xx) and unreachable hosts are left out of the percentages. “AI crawlers” in “name at least one AI crawler” excludes Googlebot, Bingbot and Applebot, which are general search engines. An llms.txt counts as present when /llms.txt returns HTTP 200 with a non-HTML body whose first line is a Markdown heading, as the llmstxt.org format requires.
Crawlers tracked: GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, Claude-SearchBot, Claude-User, PerplexityBot, Perplexity-User, Googlebot, Google-Extended, Bingbot, Applebot, Applebot-Extended, meta-externalagent, meta-externalfetcher, Amazonbot, MistralAI-User, CCBot, Bytespider, DuckAssistBot.
Limits. robots.txt is a request, not an access control: it says what a site asks, not what crawlers do (some user-triggered agents may not apply it, per their operators). Many sites also block AI crawlers at the firewall or CDN level (for example with Cloudflare), which robots.txt does not show. Results are snapshots taken once a week.
Data source citation. Ranking from the Tranco list 947V2 generated on 2026-11-14. Victor Le Pochat, Tom Van Goethem, Samaneh Tajalizadehkhoob, Maciej Korczyński and Wouter Joosen. “Tranco: A Research-Oriented Top Sites Ranking Hardened Against Manipulation.” In Proceedings of the 26th Network and Distributed System Security Symposium (NDSS 2019). https://doi.org/10.14722/ndss.2019.23386